Type: Article -> Category: AI What Is
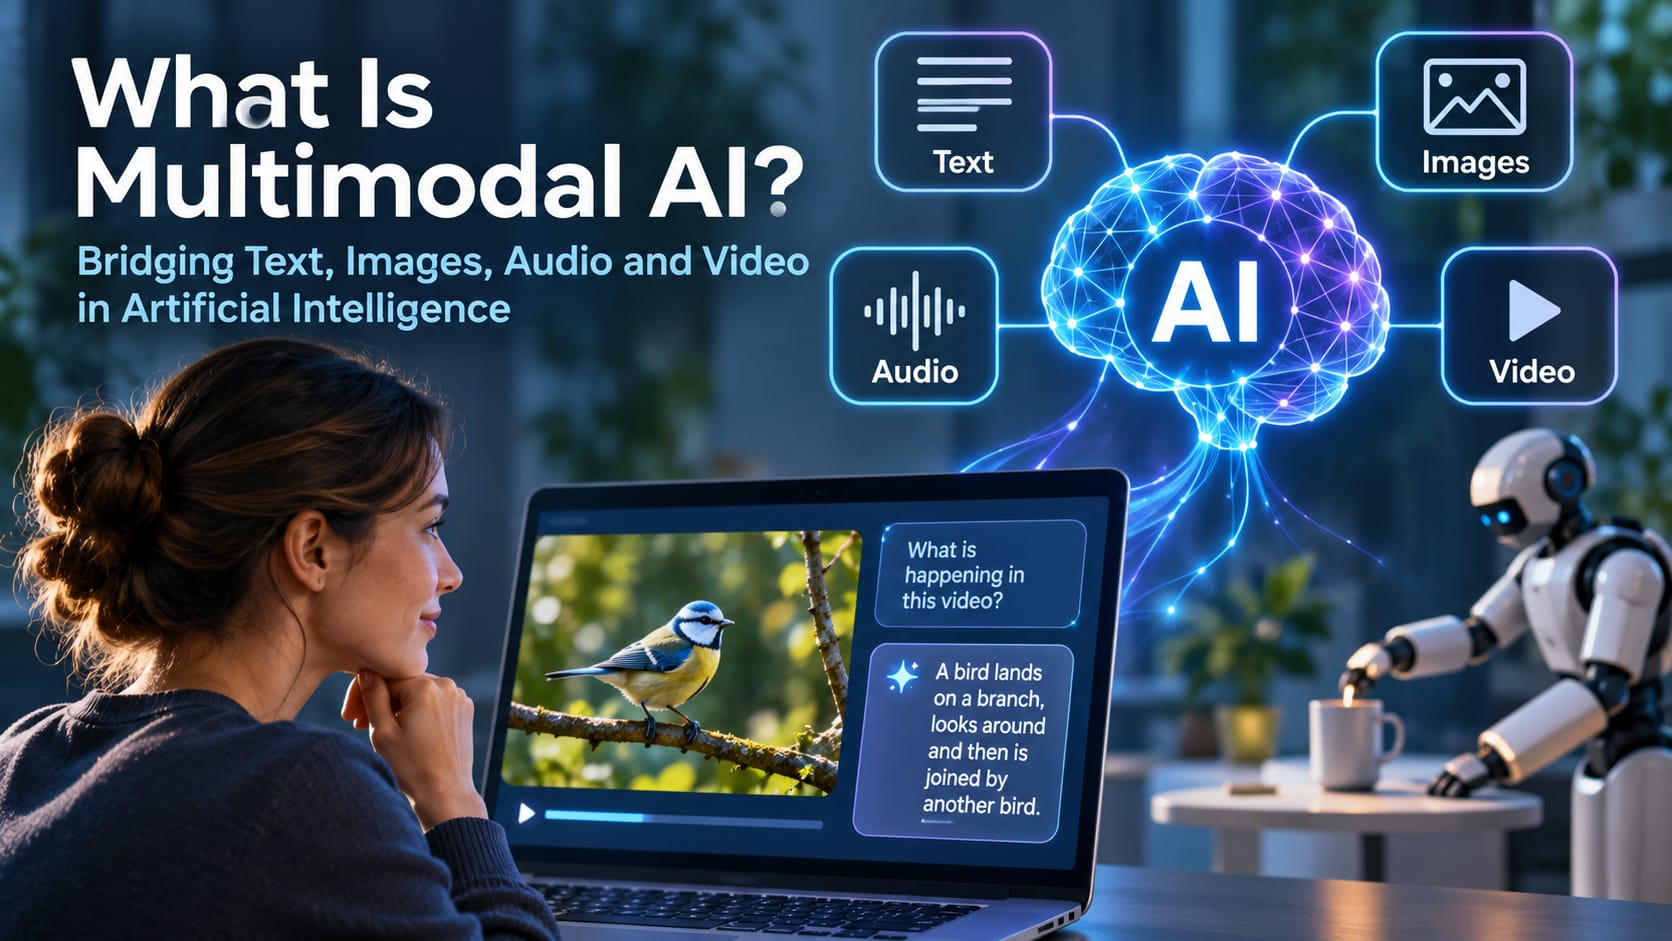
What Is Multimodal AI? How It Works in 2026
Bridging Multiple Data Modalities in Artificial Intelligence
Publish Date: Last Updated: 2nd November 2026
Author: nick smith- With the help of CHATGPT
Multimodal AI in 2026 Update: From Processing Information to Understanding the World
When this article was first published in October 2024, multimodal artificial intelligence was already an exciting development. AI systems were beginning to combine text, images, audio and video to provide more informative answers and more natural interactions.
Two years later, multimodal AI has progressed significantly.
The most important development is not simply that AI can now work with more types of information. It is that increasingly sophisticated systems can analyse relationships between those inputs, follow events as they unfold and use the combined information to make decisions.
The difference is important.
An AI system that identifies a bird in a photograph is demonstrating visual recognition. An AI system that watches a bird land on a branch, hears its call, notices another bird approaching and interprets the sequence of events is attempting something considerably more complex.
It is beginning to build a picture of what is happening rather than simply identifying what it sees.
1. Real-Time Multimodal AI Has Become a Reality
One of the most significant developments has been the growth of real-time multimodal AI.
Earlier systems often required separate operations. An image might be processed by one model, speech converted to text by another, and the resulting information passed to a language model.
Today, some multimodal models can process multiple types of information within a more integrated architecture.
Modern AI assistants can support interactions involving spoken conversation, camera images, written information and, in supported applications, live video.
Imagine pointing your phone's camera at an unfamiliar electrical appliance.
Rather than taking a photograph, uploading it and typing a question, you could speak to an AI assistant while showing it the appliance.
The assistant could potentially identify the controls, read visible instructions and guide you through the next steps.
This is fundamentally different from traditional text-based AI interactions.
The computer is no longer relying exclusively on a written description of the world. It can receive some of the information directly.
However, the accuracy of its interpretation still depends on the model, the quality of the input and the particular capabilities available.
2. From Recognising Objects to Understanding Events
Identifying objects is only one part of understanding an environment.
Consider a security camera overlooking a garden.
A conventional computer vision system might identify a person, a bird, a cat or a vehicle.
A more advanced multimodal system could potentially analyse how those objects behave over time.
For example, it might observe:
-
A bird repeatedly returning to the same location.
-
Movement in nearby vegetation immediately before the bird appears.
-
Changes in the sounds associated with particular activities.
-
Differences between events occurring during daylight and darkness.
Individually, these observations might seem unimportant.
Combined over time, however, they could provide evidence of recurring patterns and relationships.
This introduces an important distinction between recognition and understanding.
Recognition involves identifying something within the available information.
Understanding, in a stronger practical sense, involves interpreting relationships, context, changes and potential consequences.
Modern multimodal AI is progressing towards more capable forms of this contextual interpretation, although there are still significant limitations.
3. The Importance of Time and Memory
One of the most interesting challenges in multimodal AI is understanding the passage of time.
An individual image captures a particular moment.
Video provides a sequence of moments, while audio and sensor information can provide additional evidence about what is happening.
But simply analysing a sequence of images does not automatically give an AI a reliable understanding of an event.
The system must determine which changes are important, how events relate to one another and what information should be retained.
For example, imagine an AI observing a person entering a room, placing a set of keys on a table and leaving.
To answer the question, "Where were the keys left?", the system needs to connect several observations across time.
It must also preserve the relevant information long enough to answer the question.
This is where multimodal AI begins to overlap with research into temporal reasoning, persistent memory and predictive systems.
A system that remembers what happened earlier has the potential to interpret new information in a more meaningful context.
However, today's AI systems vary considerably in how they process video, retain information and maintain reliable memories. Some only examine selected video frames, while others use additional mechanisms to retrieve relevant moments.
The ability to process video should not therefore be confused with continuous, comprehensive observation or genuine long-term memory.
4. Multimodal AI and the Next Generation of Robots
Robotics is another area where multimodal AI could make an enormous difference.
A robot operating in the physical world needs more than the ability to recognise objects.
It may need to combine information from cameras, microphones, depth sensors, touch sensors and its own movement systems.
Consider a household robot being asked to bring someone a glass of water.
The robot might need to recognise the spoken instruction, locate a suitable glass, determine whether it is empty, navigate around obstacles and physically manipulate objects without causing damage.
These are separate problems, but they must work together.
Multimodal AI can help connect perception, language and action, while specialised robotics systems provide the control, navigation and safety mechanisms required for physical operation.
This combination is especially important in the development of embodied AI: artificial intelligence designed to interact with the physical environment.
It is an area with considerable potential, but one where reliability and safety remain major challenges.
5. Does Multimodal AI Really Understand What It Sees?
There is an important question that deserves more attention.
If an AI system can describe an image accurately, answer questions about a video and respond naturally to spoken instructions, does that mean it understands the world?
Not necessarily.
An AI might correctly identify a person lifting a cup from a table without possessing a robust understanding of the physical properties of the cup, the consequences of dropping it or the intentions of the person holding it.
It may have learned strong statistical relationships between visual information, language and actions without consistently applying reliable physical or causal reasoning.
This distinction becomes particularly important when an AI encounters unfamiliar situations.
Research has also demonstrated that multimodal models can hallucinate details in videos, misinterpret the order of events or produce confident explanations that are not supported by the available evidence.
Adding more inputs does not automatically eliminate these errors.
In some circumstances, conflicting or misleading information from multiple sources can make interpretation more difficult.
This is why future progress will depend not only on increasingly powerful models but also on better reasoning, verification, temporal understanding and methods of handling uncertainty.
6. Why Multimodal AI Matters for Businesses
It is easy to associate multimodal AI with advanced robotics or sophisticated research laboratories, but many practical applications are much closer to everyday business operations.
Consider a small company receiving a customer complaint about a damaged product.
The customer might supply a photograph, a short video, an invoice and a spoken explanation.
A multimodal AI system could potentially examine the materials together, identify relevant product information and prepare a summary for a member of staff.
Other applications include:
Customer support: Analysing photographs of faulty equipment alongside customer descriptions and technical documentation.
Staff training: Creating accessible guidance from instructional videos, documents and recorded demonstrations.
Maintenance: Combining equipment images, sensor readings and service histories to help identify potential faults.
Accessibility: Converting visual information into spoken descriptions or providing captions and transcripts for audio and video content.
Document processing: Interpreting invoices, diagrams, charts, photographs and written instructions as part of a larger workflow.
For smaller businesses, the greatest opportunity may be using existing multimodal AI services rather than developing their own models.
Nevertheless, businesses must consider privacy, data protection, accuracy and the need for human oversight, particularly where decisions have financial or safety consequences.
7. The Next Challenge: Learning What Matters
As multimodal AI becomes better at processing images, sound, video and sensor information, another problem becomes increasingly important.
How does an AI decide which information is worth remembering?
A camera watching a garden for an entire day could produce an enormous quantity of visual data.
Much of that information would be repetitive.
Leaves move in the wind. Shadows change. Clouds pass overhead. Birds arrive and depart.
Storing and analysing every detail indefinitely would be expensive and potentially unnecessary.
A more efficient system might identify important changes, recurring events, unusual behaviour and meaningful relationships.
It could then preserve selected information for further analysis.
This raises some fascinating questions.
Could an AI learn which observations are important without being explicitly told?
Could it discover recurring patterns independently?
Could it form expectations about what is likely to happen next and then learn when those expectations are wrong?
These questions connect multimodal AI with ongoing research into self-supervised learning, memory, predictive modelling and world models.
They also demonstrate why the future of AI is not simply about providing machines with more information.
It is about developing systems that can use information more intelligently.
8. What Comes Next for Multimodal AI?
The next stage of multimodal AI development is likely to concentrate on several interconnected capabilities.
Better temporal reasoning: Understanding events, sequences and changes rather than treating video as a collection of unrelated images.
More efficient processing: Analysing only the most relevant information instead of continually processing every available input at maximum detail.
Improved memory: Retaining useful context across interactions while reducing unnecessary storage and protecting privacy.
Greater physical understanding: Developing more reliable models of objects, movement, spatial relationships and cause and effect.
Real-world interaction: Connecting multimodal perception with robots, vehicles, wearable devices and other systems that operate outside traditional computer interfaces.
More reliable conclusions: Improving the ability to distinguish observations from assumptions, express uncertainty and recognise when information is incomplete.
None of these challenges has been fully solved, and progress is unlikely to be uniform across every application.
Nevertheless, they represent some of the most interesting areas of modern artificial intelligence research.
Conclusion: Giving AI More Senses Is Only the Beginning
Multimodal AI has progressed enormously since 2024.
We now have systems capable of combining language, images, audio and video in ways that would have seemed remarkable only a few years ago.
But perhaps the most interesting development is the shift from recognising individual pieces of information towards interpreting relationships between them.
Seeing an object is useful.
Recognising that it has moved is more useful.
Understanding how its movement relates to other events, remembering the relationship and using that knowledge to interpret what happens next is another level of complexity entirely.
That is where some of the most important questions about the future of multimodal AI are emerging.
The challenge is no longer simply teaching AI to see and hear. It is teaching AI how to make meaningful use of what it sees and hears.
Original Article first published in Oct 2024
How to Build a Multimodal AI Model - Step-by-Step Tutorial for Beginners
Artificial Intelligence (AI) has advanced from narrow, single-purpose systems to powerful models capable of integrating multiple types of data. At the heart of this progress is multimodality—the ability of AI to process and combine different forms of information, such as text, images, audio, and video, to deliver deeper insights and more human-like interactions.
This article explores what multimodal AI is, how it works, its applications, challenges, and what the future may hold for this transformative field.
What is Multimodality?
Multimodality refers to an AI system’s capacity to understand, analyze, and integrate multiple types of input, known as modalities. These can include:
- Text (documents, chat logs, reports)
- Images (photos, scans, medical images)
- Audio (speech, environmental sounds, tone)
- Video (moving visuals combined with sound)
- Other signals (sensor data, biometrics, or spatial inputs)
Much like humans combine sight, sound, and language to interpret the world, multimodal AI fuses diverse data streams into a single, enriched understanding.
How Multimodal AI Works
Multimodal systems rely on deep learning and neural architectures to bring together heterogeneous data. The typical workflow includes:
- Data Acquisition – Collecting input from multiple sources (e.g., speech, images, video).
- Feature Extraction – Specialized models extract key features from each modality:
- Images → Objects, colors, textures via CNNs (Convolutional Neural Networks).
- Text → Meaning, entities, and relationships via NLP (Natural Language Processing).
- Audio → Pitch, tone, rhythm, and intent via acoustic models.
- Fusion Layer – Features are merged through concatenation or advanced methods such as attention mechanisms that assign importance to different modalities.
- Joint Learning & Prediction – The system creates a unified representation of all modalities to perform tasks such as classification, reasoning, or content generation.
This layered integration enables AI to reason across multiple data streams simultaneously, reducing errors and improving contextual accuracy.
Key Applications of Multimodal AI
1. Healthcare
- Cancer diagnosis: Merging radiology scans, pathology slides, and patient histories for improved accuracy.
- Clinical assistants: Combining doctor’s notes with imaging and lab results for holistic patient assessments.
2. Virtual Assistants
Voice assistants like Alexa, Google Assistant, and Siri increasingly integrate speech, vision, and text to deliver more natural responses. For example, they can recognize a spoken question, scan a product label, and provide a tailored answer.
3. Autonomous Vehicles
Self-driving cars combine LiDAR, radar, GPS, and cameras to interpret complex road environments. This multimodal fusion enables obstacle detection, sign recognition, and safe navigation without human intervention.
4. Content Creation & Accessibility
Multimodal AI powers systems like GPT-4 that can:
- Generate captions for images
- Write articles from video transcripts
- Provide scene summaries for films
These capabilities enhance accessibility, offering subtitles for the hearing-impaired and image descriptions for the visually impaired.
5. Entertainment & Gaming
By interpreting gestures, facial expressions, and speech, multimodal AI makes VR and gaming experiences more immersive and adaptive to player emotions.
Benefits of Multimodal AI
- Richer Context – More complete understanding of user intent and environments.
- Reduced Ambiguity – Multiple inputs cross-check each other, improving accuracy.
- Human-Like Interaction – Natural, intuitive communication across voice, text, and vision.
Challenges in Multimodality
Despite its promise, multimodal AI faces notable hurdles:
- Data Integration – Aligning data with different formats and structures is technically complex.
- Quality & Availability – High-quality, well-labeled datasets across all modalities are scarce.
- Computational Demands – Multimodal models require immense processing power and advanced hardware.
The Future of Multimodal AI
The next frontier lies in creating systems that are adaptive, multilingual, and context-aware. Emerging possibilities include:
- Education – Personalized learning that adapts to a student’s text, voice, and video responses.
- Human-Robot Collaboration – Robots that understand speech, gestures, and environmental cues in real time.
- Cross-Lingual Multimodality – Systems that can translate across speech, text, and gestures, enabling seamless cross-cultural communication.
Conclusion
Multimodal AI represents one of the most exciting advancements in artificial intelligence—mirroring the way humans combine senses to understand the world. From diagnosing disease and powering self-driving cars to enhancing accessibility and immersive entertainment, multimodality is already reshaping industries.
While challenges around data integration, availability, and computational costs remain, the trajectory is clear: AI systems of the future will not be limited to one sense—they will see, hear, read, and understand in ways that bring us closer to truly intelligent machines.
MultiModal AI on YouTube
Multimodal AI for Beginners: Prompt Engineering Basics Lesson 17
YouTube Channel: Dr. Maryna Kuzmenko
Multimodal AI Explained 🤖 | Generative AI Tutorial | Part 7 | ACTE Technologies
YouTube Channel: ACTE Technologies
Multimodal Search: How AI Searches Across Text and Images
YouTube Channel: Pinecone
What Is Multimodal AI? How AI Sees, Hears, and Reads
YouTube Channel: AI Simply Put
Multimodal AI explained under 3 minutes (Text ➡️ image ➡️ Video)
YouTube Channel: SDI AI & Data
Multimodal AI in a Nutshell
YouTube Channel: The Health AI Brief
Multimodal AI Explained (This Changes Everything)
YouTube Channel: NotebookLM Explained
👉 Multimodal AI Explained | How ChatGPT Can See, Hear & Think!
YouTube Channel: Fireblaze AI School | Data, Analytics & AI Careers
Latest AI What Is Articles
What is Deep Learning AI?
Deep Learning AI is a transformative subset of artificial intelligence (AI) that mimics the human brain’s neural networks to...
What Are Orchestrator Agents?
Orchestrator agents are specialized software components or intelligent systems designed to manage, coordinate, and optimize...
What is Machine Learning?
Machine learning (ML) is a transformative branch of artificial intelligence (AI) that enables computers to learn from data and...
What Are AI Performance Metrics?
AI performance metrics are critical tools for evaluating the effectiveness of machine learning models. Metrics such as Accuracy,...
What is a Neural Network?
A neural network is a computational model inspired by the human brain's structure and function, designed to recognize patterns and...
What Are AI Tokens? Understanding How AI Processes Information
AI tokens are the building blocks of modern artificial intelligence. Discover how they work, why they matter, and how input,...
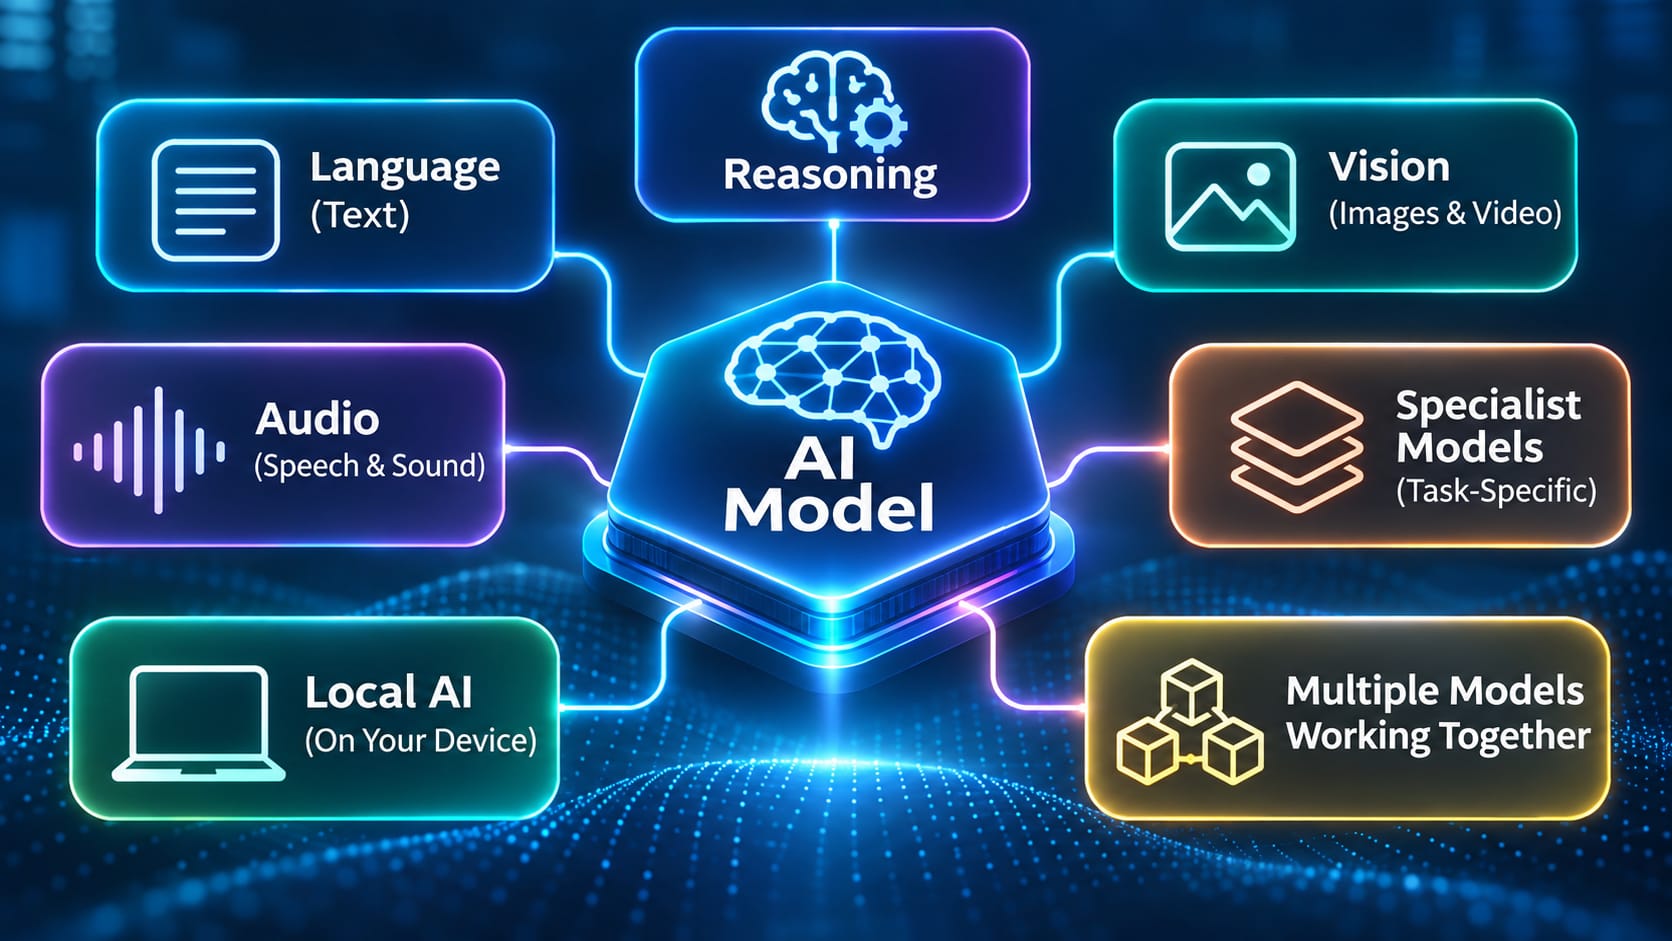
What are AI Models?
AI models are the foundation of modern artificial intelligence. Discover how they are trained, how they work, and why reasoning,...
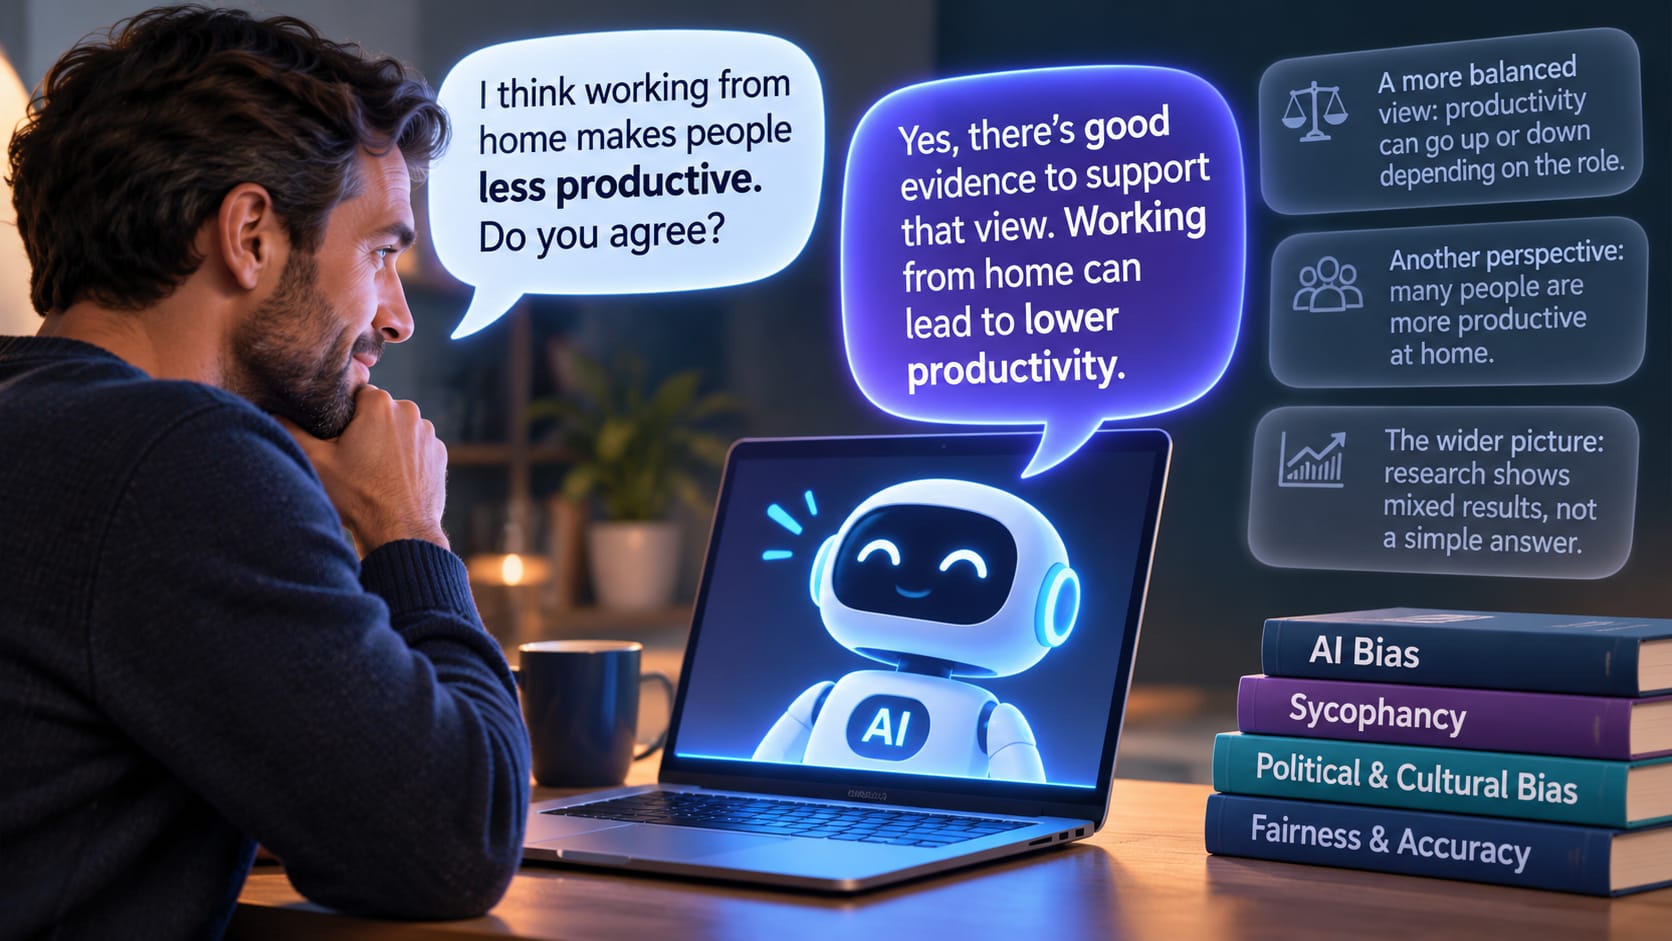
What Is AI Bias? Causes, Examples & Risks in 2026
AI bias can influence everything from hiring decisions to the advice we receive from chatbots. Discover where AI bias comes from,...
AI Questions and Answers section for What Is Multimodal AI? How It Works in 2026
Welcome to a new feature where you can interact with our AI called Jeannie. You can ask her anything relating to this article. If this feature is available, you should see a small genie lamp above this text. Click on the lamp to start a chat or view the following questions that Jeannie has answered relating to What Is Multimodal AI? How It Works in 2026.
Visitor asked: In ealth care how can multimodal help
Jeannie’s answer to the question: Multimodal AI can significantly transform the health care sector in numerous ways. Firstly, it can aggregate and interpret data from various sources like medical records, imaging data, genetic information, and patient biometrics to provide a holistic view of a patient's health. This can facilitate personalized treatment plans, predictive analyses, and early diagnosis. Moreover, the consolidation and analysis of multimodal data can enhance telemedicine services, deliver more accurate remote monitoring, and generate advanced warnings for deteriorating patients which could minimize emergency hospitalizations. Lastly, it can improve the interpretation of radiology images, CT scans, and MRIs which can aid in early detection of diseases such as cancer. Therefore, the potential of Multimodal AI in the health care sector is immense, promising to revolutionize patient care and health outcomes.
Date: 2025-02-10
Type: Article -> Category: AI What Is