Type: Article -> Category: Actionable AI
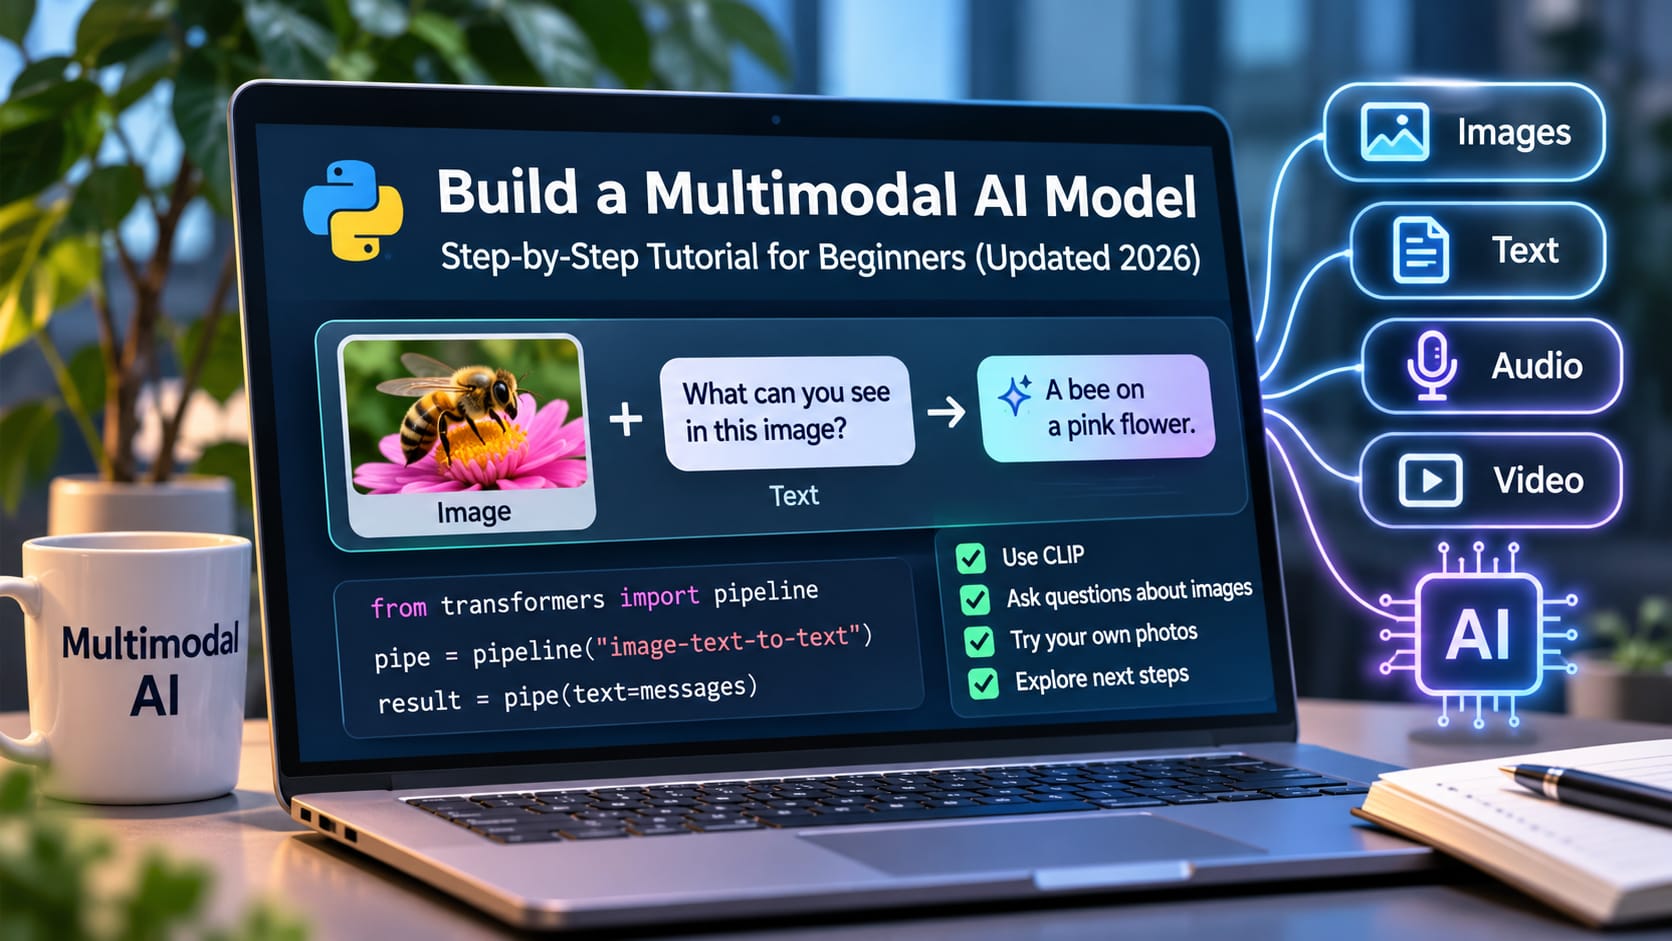
How to Build a Multimodal AI Model: Step-by-Step Tutorial for Beginners Update Nov 2026
Publish Date: Last Updated: 2nd November 2026
Author: nick smith- With the help of CHATGPT
Artificial intelligence has developed far beyond systems that simply accept a written question and return a written answer. Today's multimodal AI models can work with images, text, speech, video and other forms of information, opening up possibilities that would have required specialist knowledge and expensive computing equipment only a few years ago.
But what if you wanted to build something yourself?
The good news is that you don't need to create an enormous AI model from scratch to begin experimenting. Thanks to freely available models, Python libraries and cloud computing platforms, beginners can now build their own multimodal AI applications.
In this updated tutorial, we're going to start with something simple: showing an AI model an image and asking it to compare different descriptions.
Then we'll take things further by using a more modern vision-language model that can answer questions about what it sees.
Finally, we'll explore how to customise your application, how fine-tuning differs from simply using an existing model, and what you might build next.
You won't need to be an AI expert, and you won't need to spend thousands of pounds on hardware.
All you need is a willingness to experiment, a little patience, and enough curiosity to ask: What else could I make this do?
Let's get started.
How to Build a Multimodal AI Model help from YouTube
Build a Multimodal AI App in Python (Beginner Project)
YouTube Channel: Tech With Tim
Multimodal RAG Full Tutorial: Build a Visual AI Agent (LangChain, OpenCV & Gemini)
YouTube Channel: netseeker
Build real-time multimodal agents with Gemini and Pipecat
YouTube Channel: Google for Developers
Building Multimodal AI Agents From Scratch — Apoorva Joshi, MongoDB
YouTube Channel: AI Engineer
Original Article first published in April 2025
Introduction
In today’s AI world, it’s no longer enough for machines to just read or see—they need to do both (and more). That’s where Multimodal AI comes in.
Multimodal AI refers to models that can understand and generate content from multiple types of data—like text, images, audio, and even video—at the same time. Think of it as building an AI that can not only read your message but also see the photo you attached and respond appropriately. View our article on What is MultiModal
In this tutorial, you’ll learn:
✅ What Multimodal AI is
✅ Real-world examples of where it’s used
✅ How to build a simple Multimodal AI model using Python
✅ What tools and datasets you need
✅ How to run it all on Google Colab (free!)
✅ How to apply it in areas like education, healthcare, and content creation
💡 No deep AI background? No problem. This guide is designed to be beginner-friendly and easy to follow.
🗂️ Table of Contents
- What is Multimodal AI?
- Tools You’ll Use
- Hands-On: Building a Multimodal Model
- Beyond Basics: Fine-Tuning or Customizing
- Use Cases
- FAQ
- Conclusion
🧩 What Is Multimodal AI?
Multimodal AI is a type of artificial intelligence that can understand and generate information from more than one kind of input, also known as modalities.
The most common modalities are:
- 📝 Text – written language (like this sentence).
- 🖼️ Images – photos, drawings, screenshots.
- 🔊 Audio – speech, music, sound effects.
- 🎥 Video – sequences of images with audio and motion.
- 👁️🗨️ Sensor data – from devices like self-driving cars or smartwatches.
Traditional AI models are “unimodal”—they only handle one type of data. For example:
- A text-based chatbot like GPT-3.
- An image classifier that labels photos.
- A speech-to-text app like Whisper.
But Multimodal AI can take a combination of inputs—like an image and a question—and respond intelligently based on both.
🚀 Real-World Examples of Multimodal AI
Here’s where you’ve already seen it in action:
| Use Case | Description |
|---|---|
| 🖼️ Image Captioning | AI looks at an image and writes a description: “A dog jumping in the grass” |
| ❓ Visual Question Answering | You ask: “What color is the cat?” and the AI looks at the image to answer “gray” |
| 🔍 Image + Text Search | Type “red shoes” and AI finds matching images across the web or in a database |
| 📹 Video Content Analysis | AI breaks down video scenes, identifies faces, actions, or even sentiment |
🤖 Famous Models That Use Multimodal Learning
- CLIP (OpenAI): Connects images and text for powerful search and understanding.
- DALL·E: Generates images from text prompts.
- GPT-4V (Vision): Understands images and combines them with text responses.
- Google Gemini: Google's multimodal LLM designed to handle a mix of data inputs.
💡 Why Is It So Important?
Multimodal AI makes machines more human-like in how they process information. Humans naturally combine what we see, hear, and read to understand the world—and now AI can too.
This opens doors to better:
- Virtual assistants.
- Educational tools.
- Accessibility tech (e.g., for the visually impaired).
- Smart search engines.
- Creative design tools.
Download the Free Multimodal AI Google Colab Notebook
Want to try building your own multimodal AI application without installing Python on your computer?
We've created a free, beginner-friendly Google Colab notebook containing all three practical experiments from this tutorial.
Follow the instructions, run the code and discover how AI can compare images with text, answer questions about photographs and analyse your own pictures.
Download the Free Multimodal AI Notebook (2026)
No previous AI development experience required. Free to download and experiment with.
How to use this Colab Notebook
- Download the
.ipynbfile (above file). - Visit Google Colab.
- Select File → Upload notebook.
- Upload the downloaded file and run the cells in order.
🛠️ Tools and Technologies You’ll Use
To build your first Multimodal AI model, you don’t need a powerful computer or expensive software. Everything can be done using free tools and cloud platforms like Google Colab.
Here’s what you’ll use:
🐍 Python
Python is the go-to language for AI and machine learning. It's readable, flexible, and supported by tons of libraries we’ll use throughout this tutorial.
🤗 Hugging Face Transformers
This is one of the most popular libraries for loading pretrained models—like CLIP, BLIP, and other multimodal architectures.
Command (bash)
pip install transformers
🔥 PyTorch
PyTorch is a deep learning framework that makes it easy to train and run neural networks. It’s what many models under the hood (like CLIP) use.
Command (bash)
pip install torch torchvision
📝 Tip: If you're using TensorFlow instead, you can still follow along conceptually.
🖼️ PIL / OpenCV
These are image processing libraries. You’ll use them to load and manipulate image files before passing them into your AI model.
Command (bash)
pip install pillow
🌍 Google Colab
Google Colab is a free online environment where you can write and run Python code in the cloud—with access to GPUs!
- No installs required.
- You can share links to your code.
- Works right in your browser.
📚 Datasets
We’ll start with simple examples using built-in or small demo datasets, but if you want to go further, check out:
- COCO (Common Objects in Context): Text + image data.
- Flickr8k/30k: Images with captions.
- VQA Dataset: Visual question answering pairs.
🔄 Optional APIs If you want to explore advanced models (like GPT-4 with vision), you can use APIs like:
- OpenAI’s API (for GPT-4V).
- Google Gemini API (if publicly available).
These usually require API keys and may not be free, so we’ll focus on fully open tools for the core tutorial.
🧪 Hands-On: Building a Multimodal Model with CLIP
In this part of the tutorial, you’ll:
- Load a pre-trained multimodal model (CLIP).
- Feed it an image and a few text prompts.
- See how it ranks which caption best matches the image.
We’ll be using Google Colab, so you won’t need to install anything locally.
This free notebook contains three exercises:
- CLIP: Match an image to written descriptions.
- SmolVLM: Ask an AI to describe an image.
- Your own photo: Upload an image and ask a question about it.
How to use: Open the .ipynb file in Google Colab, then click Runtime → Run all, or run each code cell with the ▶ icon. An internet connection is needed to install packages and download the model weights. The notebook does not train models or update their weights.
Hardware: Start with a CPU runtime. A GPU may make the second experiment faster, but free GPU availability is not guaranteed. The first run downloads model files, which can take time.
Privacy: Don't upload sensitive or personal images unless you understand and accept the cloud environment's data-handling arrangements.
Step 1 — Install Python packages
Run this cell first. If Colab asks you to restart the runtime after installing packages, restart it and run from Step 2.
%pip -q install -U "transformers>=4.52,<6" torch pillow requests accelerateStep 2 — Download a sample image
We will use a public demonstration image of a bee on a flower.
from io import BytesIO
import requests
from PIL import Image
from IPython.display import display

IMAGE_URL = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
response = requests.get(IMAGE_URL, timeout=45)
response.raise_for_status()
image = Image.open(BytesIO(response.content)).convert("RGB")
# Keep the demo small enough for an introductory notebook
image.thumbnail((800, 800))
display(image)
Experiment 1 — Compare an image with text using CLIP
CLIP assigns each description a relative matching score. The scores below are not proof that any caption is true; the supplied alternatives influence the percentages.
import torch
from transformers import CLIPModel, CLIPProcessor

clip_id = "openai/clip-vit-base-patch32"
clip_model = CLIPModel.from_pretrained(clip_id)
clip_processor = CLIPProcessor.from_pretrained(clip_id)
clip_model.eval()

descriptions = [
    "A bee sitting on a flower",
    "A dog running through a field",
    "A car parked on a road",
    "A person riding a bicycle",
]

inputs = clip_processor(
    text=descriptions, images=image, return_tensors="pt", padding=True
)
with torch.inference_mode():
    output = clip_model(**inputs)
    scores = output.logits_per_image.softmax(dim=1)[0]

for caption, score in sorted(zip(descriptions, scores.tolist()), key=lambda item: item[1], reverse=True):
    print(f"{score:6.1%}  {caption}")
Try it: Change the descriptions and rerun the CLIP cell. What happens when none of your descriptions is accurate?
Experiment 2 — Ask a vision-language model about the image
We'll load SmolVLM-256M-Instruct, a compact image-to-text model. It generates answers in words instead of comparing a predefined list of captions.
The model can still make mistakes or invent details. Treat generated descriptions as suggestions, not verified facts.
from transformers import pipeline
vlm_id = "HuggingFaceTB/SmolVLM-256M-Instruct"
# Automatically choose GPU when available, otherwise CPU.
vlm = pipeline("image-text-to-text", model=vlm_id, device=0 if torch.cuda.is_available() else -1)
print("Vision-language model ready on", "GPU" if torch.cuda.is_available() else "CPU")
def ask_about_image(picture, question, max_new_tokens=100):
messages = [{
"role": "user",
"content": [
{"type": "image", "image": picture},
{"type": "text", "text": question},
],
}]
results = vlm(text=messages, max_new_tokens=max_new_tokens, return_full_text=False)
answer = results[0]["generated_text"]
# On some library versions, generated_text may be a structured list.
if isinstance(answer, list):
answer = " ".join(part.get("text", "") for part in answer if isinstance(part, dict))
return str(answer).strip()
print(ask_about_image(image, "Describe what you can see in this image."))Try it: Change the question to What colours are visible? or Write a short alt text for this image.
Experiment 3 — Upload your own photograph (optional)
The upload dialog works in Google Colab. Select a .jpg, .jpeg, .png, or .webp image. The notebook uses only the first uploaded file. Uploaded files are temporary in the Colab runtime.
Only upload images you are comfortable processing in Colab.
from google.colab import files

uploaded = files.upload()
if not uploaded:
    print("No file selected. Rerun this cell when you're ready.")
else:
    filename = next(iter(uploaded))
    with Image.open(BytesIO(uploaded[filename])) as uploaded_image:
        my_image = uploaded_image.convert("RGB")
    my_image.thumbnail((800, 800))
    display(my_image)
    print("Uploaded:", filename)
if "my_image" in globals():
question = "Describe the main objects in this photograph."
print("Question:", question)
print("Answer:", ask_about_image(my_image, question, max_new_tokens=120))
else:
print("Upload an image in the previous cell first.")What have you built?
- Experiment 1: A program that compares an image with candidate captions (CLIP).
- Experiment 2: A program that generates a description or answer about an image (SmolVLM).
- Experiment 3: The same application using your own image.
These examples run pretrained models. They do not train or fine-tune the models. To fine-tune a model you need an appropriate dataset, a supported training setup and a separate evaluation process.
Troubleshooting
- Package/import error? Restart the runtime after installation and run cells again from the top.
- Out of memory? Restart the runtime, use smaller images, or switch to a suitable GPU runtime if available.
- Slow second experiment? CPU inference can be slow, and model download speeds depend on connectivity.
- A strange answer? Small vision-language models can hallucinate. Try a simpler question and check the original image.
- Upload fails locally? The upload step is designed for Colab. For local Python, replace it with
Image.open("/path/to/photo.jpg").convert("RGB").
Taking Your Multimodal AI Project Further: Customisation, Fine-Tuning and Training
Now that you've built a simple multimodal application, you might be wondering how to make it do something more specialised.
Perhaps you want an AI system that recognises products in your business, describes photographs automatically, or understands images from a particular environment.
There are several ways to approach this, and it's important to understand the differences.
1. Using a Pretrained Model
This is what we've done in our first two experiments.
We download a model that has already learned from large amounts of data and use it to process our own information.
We aren't changing the model's underlying knowledge or weights.
2. Customising the Application
Before attempting to train anything, we can make our application more useful by changing how it works.
For example, we might add an interface where users upload photographs, provide specific instructions, compare different images or save results to a database.
We could also connect the vision model to other software, allowing it to participate in a larger application.
This is often the most practical starting point for a small business or independent developer.
3. Fine-Tuning an Existing Model
Fine-tuning involves taking a pretrained model and continuing its training with carefully prepared examples.
For instance, a business might want a model to recognise specialised equipment or produce descriptions in a consistent format.
This requires suitable training data, an appropriate model, additional software and enough computing resources.
Parameter-efficient approaches such as LoRA can reduce the amount of training required, but they still involve genuine changes to trainable model parameters.
Fine-tuning should also include a separate evaluation dataset to establish whether the model has actually improved.
4. Training a Multimodal Model From Scratch
This is a much larger undertaking.
Instead of starting with a model that already understands images and language, you build and train the architecture yourself.
You'll need to consider image encoders, language processing, how information from different modalities is combined, training objectives, data quality and evaluation.
Training a competitive general-purpose multimodal model can require enormous datasets and computing resources.
However, small experimental models are still an excellent learning opportunity.
Our recommendation for beginners: Start by building a working application with a pretrained model. Learn how it behaves, identify its limitations and only consider fine-tuning when you have a specific problem that existing models cannot solve adequately.
🌍 Real-World Applications of Multimodal AI
Multimodal AI isn’t just a cool research concept—it’s powering real innovations in the apps, tools, and platforms we use every day. Here are some of the most exciting and impactful use cases:
🧑🏫 1. Education & e-Learning
Multimodal AI helps create smart, interactive learning experiences. For example:
- Generate visual explanations from text-based concepts.
- Answer questions based on diagrams or charts.
- Power virtual tutors that can read a student’s question and the attached worksheet.
💡 Imagine asking your AI assistant: “What does this graph mean?”—and it explains it back in plain English.
🩺 2. Healthcare & Diagnostics
Multimodal AI is being used to combine medical imaging with clinical notes for better diagnosis.
Examples:
- Detecting conditions from X-rays with supporting text.
- Generating patient summaries that merge lab reports with visuals.
- AI-assisted ultrasound interpretation.
🧠 It sees the scan + reads the symptoms = smarter, faster analysis.
🛍️ 3. E-Commerce & Retail
AI that understands product images and descriptions can:
- Auto-generate product captions.
- Recommend similar products by “visual + textual” similarity.
- Improve search results using visual cues.
🛒 Type “green running shoes” and get smart results across the store catalog.
♿ 4. Accessibility Tools
Multimodal AI can help users with disabilities by:
- Describing images for the visually impaired.
- Translating sign language from video into text.
- Converting complex data visuals into spoken summaries.
🔊 “There is a person in the image holding a cup of coffee.”
🎥 5. Content Creation & Social Media
Creators are using AI that understands both visuals and words to:
- Auto-caption videos and photos.
- Create content summaries.
- Match background music with scene mood.
🎨 Generate thumbnails, hashtags, and even script suggestions based on your video.
🔍 6. Smart Search Engines
Modern search goes beyond keywords. Multimodal AI powers:
- Visual search (“search by image”).
- Text+image hybrid queries.
- Semantic search that understands content meaning.
📸 Drag an image into the search box and type “similar but red”—the AI gets it.
🚀 Bonus: Other Cool Applications
- Multimodal chatbots that respond to images, text, and even voice.
- Autonomous vehicles that process video, lidar, and voice commands.
- Multimodal emotion recognition from facial expression + voice tone + text.
Frequently Asked Questions About Building Multimodal AI Models
1. What is a multimodal AI model?
A multimodal AI model is an artificial intelligence system designed to process or work with more than one type of information, such as text, images, audio or video.
For example, a vision-language model can examine a photograph and answer written questions about what it sees. More advanced multimodal models can combine speech, images and text within the same interaction.
Unlike traditional text-only AI, multimodal models can use information from different sources to interpret a question or perform a task.
2. Can beginners build their own multimodal AI model?
Yes. Beginners can build multimodal AI applications using existing pretrained models without needing advanced machine learning knowledge.
Tools such as Python, Hugging Face Transformers and Google Colab make it relatively straightforward to load an existing model and start experimenting with images and text.
However, there is an important distinction between building an application using a pretrained model and training an entirely new AI model from scratch.
For most beginners, using and customising an existing model is the best starting point.
3. Do I need to know Python to build a multimodal AI application?
You don't necessarily need to be an experienced programmer, but basic Python knowledge is helpful.
Python is widely used for AI development because it offers libraries such as PyTorch, Transformers and Pillow.
Beginners can follow ready-made code examples using Google Colab, gradually learning what each instruction does.
You can also use AI coding assistants to help explain code, identify errors and experiment with new features. However, it's still important to understand how your application works.
4. Can I build a multimodal AI model for free?
Yes, you can experiment with many multimodal AI models without purchasing expensive software or paying for commercial APIs.
Hugging Face provides access to numerous open-weight models, while Google Colab offers a free computing environment with usage limits.
For introductory projects involving image classification, image-text matching and basic visual question answering, free tools may be sufficient.
However, free computing resources are limited, and access to GPUs isn't guaranteed. Larger models, fine-tuning and commercial cloud services may involve additional costs.
5. What hardware do I need to run a multimodal AI model?
The hardware requirements depend on the size of the model and what you want it to do.
Small vision-language models can sometimes run on ordinary computers using their CPUs, although performance may be slower than on a dedicated graphics processor.
A compatible GPU with sufficient video memory can significantly improve performance, particularly for larger models or training.
For beginners who don't have suitable hardware, cloud platforms such as Google Colab provide an alternative.
You don't need a powerful AI workstation to begin learning.
6. What is the difference between CLIP, BLIP and modern vision-language models?
CLIP and BLIP are both important developments in multimodal AI, but they perform different tasks.
CLIP is designed to learn relationships between images and text. It is useful for comparing images with descriptions, image retrieval and classification using candidate text labels.
BLIP is a family of models developed for tasks such as image captioning, visual question answering and image-text retrieval, depending on the model version and configuration.
Modern instruction-following vision-language models can accept images alongside natural-language questions and generate conversational responses.
In this tutorial, we use CLIP to demonstrate image-text matching and a compact vision-language model to demonstrate visual question answering.
7. What is the difference between using, fine-tuning and training an AI model?
These terms describe three different approaches.
Using a pretrained model means downloading or accessing an existing model and asking it to perform tasks without modifying its learned parameters.
Fine-tuning means continuing the training of an existing model using additional examples to improve its performance on a particular task or domain.
Training from scratch means creating and training a model without starting from pretrained weights.
For most beginners and small businesses, using an existing model is considerably more practical than training one from scratch.
8. Can multimodal AI run locally without an internet connection?
Yes. Some multimodal AI models can run entirely on your own computer after the necessary model files and software have been downloaded.
This is particularly useful for privacy-sensitive applications, experimentation and situations where internet connectivity is unreliable.
However, not all AI applications run locally. Some depend on commercial APIs or external services.
If privacy is important, check that the application genuinely performs its processing on your own hardware rather than sending images or other data to an external server.
9. Can I train a multimodal AI model using my own images?
Yes, provided the model supports training or fine-tuning and you have suitable data, software and computing resources.
For example, you might fine-tune a compatible vision-language model using photographs of specialised equipment and carefully prepared descriptions.
However, simply uploading photographs to an AI application or asking questions about them does not mean the model is learning from those images or changing its weights.
For many projects, using a pretrained model with your own images is sufficient without any additional training.
10. Can multimodal AI understand video and audio as well as images?
Yes. Multimodal AI is not limited to image recognition.
Some models support audio, video and text, allowing them to perform tasks such as speech transcription, video summarisation, visual question answering and spoken conversations.
Video understanding is particularly challenging because the system must consider not only individual frames but also how events change over time.
Some applications handle this by combining separate models for vision, audio and language processing. Others use models designed to work across several modalities.
11. What can small businesses use multimodal AI for?
Multimodal AI offers numerous practical opportunities for small businesses.
Possible applications include automatically generating product descriptions from photographs, categorising images, extracting information from documents, assisting with visual inspections and answering questions about diagrams or equipment.
A business might also combine image recognition with its existing website, stock management software or customer support system.
The most effective starting point is usually to identify a specific problem and determine whether a pretrained model can solve it reliably.
Any system making important decisions should include appropriate testing and human oversight.
12. Can a multimodal AI model learn continuously from what it sees?
Potentially, but continuous learning is more complicated than simply connecting an AI model to a camera.
Most pretrained vision-language models do not automatically update their weights when they process new images.
An application can store observations, maintain a searchable memory, detect recurring patterns and compare new information with previous experiences without retraining the underlying model.
True continual learning involves additional mechanisms for updating what the system has learned while avoiding problems such as catastrophic forgetting.
This remains an active area of AI research and experimentation.
13. How accurate are multimodal AI models?
Accuracy varies considerably depending on the model, the quality of the input and the task being performed.
A model may correctly identify the main subject of a photograph while making mistakes about small objects, numerical quantities, text or relationships between objects.
Vision-language models can also hallucinate, generating descriptions of things that aren't actually present.
For this reason, multimodal AI should be tested with representative examples before being used in business processes or situations where mistakes could have serious consequences.
14. What is the easiest way to start building multimodal AI in 2026?
The easiest approach is to start with a small pretrained model and a clearly defined task.
For example, use CLIP to compare an image against several written descriptions, then experiment with a vision-language model that can answer questions about photographs.
Google Colab provides a convenient environment for beginners, while Hugging Face offers models, documentation and Python libraries.
Once you understand the basics, you can begin developing your own applications, experimenting with local models or investigating fine-tuning.
The important thing is to start small, build something that works, and gradually explore what else is possible.
Multimodal AI in 2026: What Has Changed?
When this tutorial was first published in April 2025, multimodal AI was already making significant progress. Since then, the tools available to ordinary developers have continued to improve.
One particularly important development has been the availability of smaller vision-language models.
These models make it possible to experiment with image understanding without necessarily relying on enormous cloud-based systems.
Developers can now choose from several approaches depending on their requirements.
Cloud-based multimodal AI: Commercial services provide access to powerful models through applications and APIs. These are useful when performance and convenience are priorities.
Open-weight multimodal AI: Models available through platforms such as Hugging Face allow developers to inspect supported architectures, run models locally and customise them under their respective licences.
Local multimodal AI: Smaller models and increasingly efficient inference techniques make it possible to process images and text on personal computers and other devices, subject to hardware capabilities.
Multimodal applications: Rather than attempting to build one model capable of everything, developers can combine different models and software components to create specialised systems.
Where Does Audio and Video Fit In?
So far, our experiments have focused on images and text.
But multimodal AI can go considerably further.
Audio-capable systems can combine speech recognition, language understanding and speech generation. Video-capable models can analyse sequences of frames, sometimes alongside audio.
Some models support several modalities within a single architecture, while other applications combine separate specialised models.
The distinction matters because a collection of connected AI tools isn't necessarily one unified multimodal model.
Nevertheless, both approaches can produce useful applications.
The Next Challenge: Understanding What Changes Over Time
Recognising an object in a photograph is useful, but understanding how something changes over time introduces additional challenges.
Imagine an AI watching a garden.
Recognising a bird is one task. Recognising that several birds repeatedly visit the same location, respond to one another and behave differently throughout the day requires additional temporal analysis and memory.
This moves the problem beyond individual image recognition towards understanding relationships, patterns and events.
And it illustrates why multimodal AI is such an exciting area for independent experimentation.
The objective isn't necessarily to build the largest model.
Sometimes, the more interesting challenge is to discover what can be achieved by combining a few relatively simple components in an intelligent way.
🎉 Conclusion: What You Can Build Next
You’ve just taken your first steps into the world of Multimodal AI—congrats!
By now, you’ve learned: ✅ What Multimodal AI is and why it matters
✅ How to use pre-trained models like CLIP
✅ How to build a working prototype that understands images and text
✅ How to fine-tune a multimodal model on your own dataset
✅ Real-world applications and inspiration for future projects
🚀 Where to Go from Here
Now that you've got the basics, here are a few ideas to keep exploring:
🔹 Build an image captioning tool for your own photos
🔹 Train a product recommendation system using both image and text metadata
🔹 Create an AI assistant that answers questions about uploaded charts, infographics, or diagrams
🔹 Start a personal AI research project using datasets like COCO or VQA
🔹 Try GPT-4V or Google Gemini if you have access, and explore advanced vision-language tasks
🙌 Help Others Learn
If you found this guide helpful:
- Share it with your peers or learning community 💬.
- Star the GitHub repo (if you host this project).
- Drop us a comment or suggestion for improvement ✍️.
💡 Final Thought
Multimodal AI isn’t just the future—it’s already here. From creative tools and virtual assistants to smarter search engines and accessible tech, the possibilities are endless.
You now have the knowledge and tools to start building your own intelligent systems that understand the world more like we do—through sight, language, sound, and context combined.
Keep experimenting. Keep learning. The frontier of AI is multimodal. 🌐🤖🔥
More Actionable AI Articles
Training Grok to Write Like You: A Detailed Guide
Grok, created by xAI, is a powerful AI designed to provide helpful and truthful answers, with a unique voice inspired by figures...
How to Create AI Videos in Minutes with Video GPT and VEED: A Step-by-Step Guide for Content Creators
If you want to create a video that can be made from stock images, video and is straight forward then this combination of ChatGPT...
How to Run a Local AI Image Generator with Stability Matrix and Stable Diffusion
AI image generation has transformed from a niche research field to a widely accessible technology, empowering creators to produce...
How to Create an AI Sprite Sheet: A Step-by-Step Guide for Game Developers
If you’re searching for a foolproof, one-click solution to create sprite sheets with AI, brace yourself for a bit of...
How to Train Your Own Local AI on Your Data
Want an AI that works with your own documents without sending everything to the cloud? Discover how to run local AI on your...
Is it possible to run your own AI using VirtualBox and Ubuntu?
I have been looking into implementing AI into my website and whilst there are many out the box options, almost all of them require...
A Newbie’s Guide to AI Animation: Myths, Facts, and Hilarious Realities
Let’s face it: AI animation is the new kid on the block, and everyone wants a piece of the action. But before you dive in thinking...
How to Get the Most Out of ChatGPT
ChatGPT, powered by OpenAI, has evolved into one of the most powerful and versatile AI tools. From assisting with content creation...
AI Questions and Answers section for How to Build a Multimodal AI Model: Step-by-Step Tutorial for Beginners
Welcome to a new feature where you can interact with our AI called Jeannie. You can ask her anything relating to this article. If this feature is available, you should see a small genie lamp above this text. Click on the lamp to start a chat or view the following questions that Jeannie has answered relating to How to Build a Multimodal AI Model: Step-by-Step Tutorial for Beginners.
Be the first to ask our Jeannie AI a question about this article
Look for the gold latern at the bottom right of your screen and click on it to enable Jeannie AI Chat.
Type: Article -> Category: Actionable AI